3 Eliciting Measures
Topics: Direct elicitation of measures from human and AI agents. Self-reports, crowd-sourcing, expert judgements.
Required reading:
- Chapter 6, Pragmatic Social Measurement
Further reading:
Self-Reported Measures
- Butler, Joseph S., et al. “Measurement error in self-reported health variables.” The Review of Economics and Statistics (1987): 644-650.
- Alan B. Krueger and David A. Schkade. “The Reliability of Subjective Well-Being Measures” Journal of Public Economics 2008 Aug; 92(8-9): 1833–1845.
Crowd-Sourcing
Expert Judgements
- Lindstädt, R., Proksch, S.-O. and Slapin, J.B. (2020) ‘When Experts Disagree: Response Aggregation and its Consequences in Expert Surveys’, Political Science Research and Methods, 8(3), pp. 580–588. doi:10.1017/psrm.2018.52.
- Steenbergen, M.R. and Marks, G. (2007) ‘Evaluating expert judgments’, European Journal of Political Research, 46(3), pp. 347–366. doi:10.1111/j.1475-6765.2006.00694.x.
LLM/AI Coding
- Gilardi, Fabrizio, Meysam Alizadeh, and Maël Kubli. “ChatGPT outperforms crowd workers for text-annotation tasks.” Proceedings of the National Academy of Sciences 120.30 (2023): e2305016120.
- Le Mens, Gaël, and Aina Gallego. “Positioning political texts with large language models by asking and averaging.” Political Analysis 33.3 (2025): 274-282.
- O’Hagan, Sean, and Aaron Schein. “Measurement in the age of llms: An application to ideological scaling.” arXiv preprint arXiv:2312.09203 (2023).
- Reiss, Michael V. “Testing the reliability of chatgpt for text annotation and classification: A cautionary remark.” arXiv preprint arXiv:2304.11085 (2023).
- Palmer, Alexis, Noah A. Smith, and Arthur Spirling. “Using proprietary language models in academic research requires explicit justification.” Nature computational science 4.1 (2024): 2-3.
- Pangakis, Nicholas, Samuel Wolken, and Neil Fasching. “Automated annotation with generative ai requires validation.” arXiv preprint arXiv:2306.00176 (2023).
3.1 Seminar
For this assignment, we are going to look at measures that relate to specific occupations (jobs). Given the topic this week, we are going to focus on measures that arise through processes of direct elicitation. The target concepts, for the purposes of this exercise are (1) how prestigious different occupations are and (2) whether different occupations should be regulated (in the sense that, in order to carry them out or to claim them as a title, one should be legally required to have certain professional qualifications or experience). Occupational prestige is the social standing or esteem that a society collectively attaches to a particular job. It reflects how people generally rank occupations in terms of respect, honor, and perceived worth, rather than any single objective feature of the work itself. This is a concept which sociologists have worked to measure since the 1940s. Occupational regulation is a policy choice, and individuals’ views on this are an example of a political attitude or policy belief of the kind frequently studied in political science. Both of these are concepts where there is not an obvious gold standard that is independent of existing beliefs and practice, and so they provide an opportunity to think about different approaches to validation.
The two concepts also allow us to practice the different approaches required to assess validity and reliability in interval-level data (occupational prestige) and binary categorical data (occupations requiring regulation).
This assignment is partially derived from results reported in a paper entitled “Occupational prestige and occupational social value in the United Kingdom: New indices for the modern British economy” by Gemma Newlands and Christoph Lutz (2024). In their study, they asked UK survey respondents the following question:
For each listed occupation below, please use the slider to indicate how you would rate the prestige of the occupation on a scale of 0 (the lowest level of prestige) to 100 (the highest level of prestige).
They report the mean and standard deviation for each of large number of occupational categories, which are defined by International Standard Classification of Occupations ISCO-08 occupational codes.
The UK government describes “regulated professions” as follows:
Some professions in the UK are regulated. This can mean there is a legal requirement to have certain qualifications or experience. Other professions are regulated by chartered bodies granting a certain status.
If a profession is regulated, you may need certain professional qualifications or experience to:
- carry out certain professional activities
- use a professional title, like ‘architect’
For many professions, the bodies that decide if you are qualified to work in a regulated profession are known as ‘regulators’. Some professions are also regulated through chartered professional bodies.
In this exercise, we are going to look at data collected from various LLMs in which they (1) rate the occupational prestige of a selected set of occupations and (2) code whether they think that these occupations ought to be “regulated professions”. We will consider the results of the prestige survey by Newlands and Lutz and the actually regulated professions in the UK as benchmarks for LLM responses, and think about what these kinds of benchmarks can and cannot tell us about the reliability and validity of the elicited measures.
The main data file for this exercise includes the average value op_mean from the Newlands and Lutz survey data, and a set of variables
prestige_gemini_3.5_flash_liteprestige_gemini_3.6_flashprestige_gemini_3.1_proprestige_chatgptprestige_chatgpt_thinkingprestige_claude_haiku_4.5prestige_claude_sonnet_5.0prestige_claude_opus_5.0
that resulted from asking these LLMs to rate the prestige of the listed occupations on a 0 to 100 scale. The LLMs were directly prompted via their chat interface, as follows:
For each listed occupation below, please rate the prestige of the occupation on a scale of 0 (the lowest level of prestige) to 100 (the highest level of prestige).
Please do not look up any existing listings or ratings of occupations, this is meant to be your assessment based on your sense of occupations and the concept of prestige.
Then this was followed by a list, in alphabetical order, of the 20 occupations.
The data file also has codings of whether the same occupations ought to be legally regulated:
regulation_gemini_3.5_flash_literegulation_gemini_3.6_flashregulation_gemini_3.1_proregulation_chatgptregulation_chatgpt_thinkingregulation_claude_haiku_4.5regulation_claude_sonnet_5.0regulation_claude_opus_5.0
Note that this coding task is not part of the Newlands and Lutz data, so there is no population survey benchmark for this part of the exercise. However, there is a variable in the data set regulated which indicates whether these occupations are actually regulated in the UK (there are some ambiguous cases, see ambiguous and note variables for details, but we will ignore this for the purposes of the assignment).
- Open the data file week-3-data-entry-template.csv that you downloaded above in Excel or in a basic text editor. It has rows for each of 20 occupational categories, and two empty columns
prestige_my_ratingandregulation_my_coding. Please take a couple minutes to go through each of the 20 occupational categories, entering your personal view as to the level of occupational prestige (on a 0-100 scale) and whether the profession ought to be regulated in the sense described above (0 = no, 1 = yes). When you are done, save the data keeping the same name and csv file format. Then load both this data file and the other data file into R and then merge them. For example, if the files are in the current R working directory, you could load and merge these as follows:
my_data <- read.csv("week-3-data-entry-template.csv")
occ <- read.csv("week-3-occupation.csv")
df <- merge(my_data,occ)
- Compare your occupational prestige ratings that you saved in
prestige_my_ratingto the average ratings from the Newlands and Lutz survey dataop_mean, treating the latter as a gold standard. On this basis, calculate the average measurement error (bias), the standard deviation (variance) of the measurement errors, and the reliability (calculated as \(\rho^2\), where \(\rho\) is the Pearson correlation) of the measure.
## [1] NA## [1] NA## [1] NAThe results are all NA above because they have been executed on the empty template file. The exact values you get will depend on your own prestige ratings.
- Do the same calculations for each of the LLM measures, again using
op_meanas the gold standard measure, and organise these into a table with rows for each LLM, and columns for bias, variance (expressed as a standard deviation) and reliability (expressed as \(\rho^2\)). What would you say in general about how the LLMs performed at this task? How did your own ratings perform relative to the LLMs?
There are various ways to do this. The approach below is not the most elegant way to do it, but it is hopefully reasonably easy to understand.
llm_prestige_variable_names <- c("prestige_gemini_3.5_flash_lite","prestige_gemini_3.6_flash","prestige_gemini_3.1_pro","prestige_chatgpt","prestige_chatgpt_thinking","prestige_claude_haiku_4.5","prestige_claude_sonnet_5.0","prestige_claude_opus_5.0")
prestige_gold_standard <- df$op_mean
llm_prestige_ratings <- df[,llm_prestige_variable_names]
rownames(llm_prestige_ratings) <- df$occupation_title
colnames(llm_prestige_ratings) <- sub("prestige_","",llm_prestige_variable_names,fixed=TRUE) # shorter variable names, not necessary to do this

# calculate each of the three quantities for each of the columns (index 2) corresponding to the different llm ratings
llm_bias <- apply(llm_prestige_ratings,2,function(x) mean(x - prestige_gold_standard))
llm_sd <- apply(llm_prestige_ratings,2,function(x) sd(x - prestige_gold_standard))
llm_reliability <- apply(llm_prestige_ratings,2,function(x) cor(x,prestige_gold_standard)^2)

error_statistics <- data.frame(
  bias = llm_bias,
  sd = llm_sd,
  reliability = llm_reliability
)

print(round(error_statistics,2))
## bias sd reliability
## gemini_3.5_flash_lite -0.10 9.11 0.90
## gemini_3.6_flash 7.40 5.12 0.95
## gemini_3.1_pro -1.55 8.30 0.94
## chatgpt 5.55 6.32 0.92
## chatgpt_thinking 7.60 6.05 0.90
## claude_haiku_4.5 1.85 6.48 0.93
## claude_sonnet_5.0 2.85 6.19 0.94
## claude_opus_5.0 -2.35 7.34 0.95On a 0-100 scale, the observed range of biases and standard deviations of the measurement errors seem pretty reasonable. Is +7 a large bias? It is difficult to say, it probably depends on what you are planning to do with the measures. The reliabilities are all 0.9 or above, which means that most of the observed variation in the gold standard is reflected in the variation of the ratings by all of the LLMs. The models all do pretty well at replicating the variation across occupations that is present in the survey results.
It is perhaps not hugely surprising that the LLMs do well at this task. The concept of occupational prestige is well studied, and there is a lot of text that the LLMs might have ingested (including the study we are using to benchmark their responses!). In addition to such direct evidence, the core idea of prestige, that people tend to think more or less highly of various jobs, is conveyed implicitly in many, many kinds of texts, and LLMs may well absorb this information through their training process as well. There is a lot of text that has relevant information on what people think about this.
- Calculate the inter-coder reliabilities for the LLM measures against one another (again, as \(\rho^2\)). How do these compare to the reliabilities that you calculated against
op_meanfor each of those measures in the previous question? Are they larger or smaller in general? If these measures have independent errors by comparison to the gold standard, would we expect the intercoder reliabilities to be higher or lower than the reliabilities versus the gold standard? Are the measurement errors relative to the gold standard correlated across the different LLM measures?
##                       gemini_3.5_flash_lite gemini_3.6_flash gemini_3.1_pro
## gemini_3.5_flash_lite                  1.00             0.96           0.97
## gemini_3.6_flash                       0.96             1.00           0.98
## gemini_3.1_pro                         0.97             0.98           1.00
## chatgpt                                0.95             0.98           0.97
## chatgpt_thinking                       0.93             0.97           0.95
## claude_haiku_4.5                       0.96             0.98           0.96
## claude_sonnet_5.0                      0.98             0.99           0.97
## claude_opus_5.0                        0.96             0.99           0.98
##                       chatgpt chatgpt_thinking claude_haiku_4.5
## gemini_3.5_flash_lite    0.95             0.93             0.96
## gemini_3.6_flash         0.98             0.97             0.98
## gemini_3.1_pro           0.97             0.95             0.96
## chatgpt                  1.00             0.99             0.97
## chatgpt_thinking         0.99             1.00             0.97
## claude_haiku_4.5         0.97             0.97             1.00
## claude_sonnet_5.0        0.97             0.96             0.98
## claude_opus_5.0          0.96             0.96             0.97
##                       claude_sonnet_5.0 claude_opus_5.0
## gemini_3.5_flash_lite              0.98            0.96
## gemini_3.6_flash                   0.99            0.99
## gemini_3.1_pro                     0.97            0.98
## chatgpt                            0.97            0.96
## chatgpt_thinking                   0.96            0.96
## claude_haiku_4.5                   0.98            0.97
## claude_sonnet_5.0                  1.00            0.99
## claude_opus_5.0 0.99 1.00diag(intercoder_reliability) <- NA # exclude self-correlations, which are always 1
# average intercoder reliability:
print(mean(intercoder_reliability,na.rm=TRUE))## [1] 0.9699862## [1] 0.9281182# measurement error correlation:
llm_measurement_errors <- apply(llm_prestige_ratings,2,function(x) (x - prestige_gold_standard))
print(round(cor(llm_measurement_errors),2))## gemini_3.5_flash_lite gemini_3.6_flash gemini_3.1_pro
## gemini_3.5_flash_lite 1.00 0.84 0.89
## gemini_3.6_flash 0.84 1.00 0.87
## gemini_3.1_pro 0.89 0.87 1.00
## chatgpt 0.81 0.89 0.82
## chatgpt_thinking 0.66 0.87 0.67
## claude_haiku_4.5 0.85 0.92 0.82
## claude_sonnet_5.0 0.93 0.92 0.86
## claude_opus_5.0 0.89 0.90 0.94
## chatgpt chatgpt_thinking claude_haiku_4.5
## gemini_3.5_flash_lite 0.81 0.66 0.85
## gemini_3.6_flash 0.89 0.87 0.92
## gemini_3.1_pro 0.82 0.67 0.82
## chatgpt 1.00 0.92 0.85
## chatgpt_thinking 0.92 1.00 0.81
## claude_haiku_4.5 0.85 0.81 1.00
## claude_sonnet_5.0 0.87 0.77 0.92
## claude_opus_5.0 0.80 0.71 0.86
## claude_sonnet_5.0 claude_opus_5.0
## gemini_3.5_flash_lite 0.93 0.89
## gemini_3.6_flash 0.92 0.90
## gemini_3.1_pro 0.86 0.94
## chatgpt 0.87 0.80
## chatgpt_thinking 0.77 0.71
## claude_haiku_4.5 0.92 0.86
## claude_sonnet_5.0 1.00 0.93
## claude_opus_5.0 0.93 1.00The average intercoder reliability between LLMs is substantially higher than the average reliability against the gold standard. If the measurement error with respect to the gold standard were independent across the different LLM measures, we would expect the intercoder reliabilities to be lower, not higher. The reason for this is that intercoder reliability is reduced by the effect of the sum of the measurement errors of both measures, whereas reliability against the target is only affected by the measurement error of a single measure. If the measurement errors are independent, then their sum will be larger. However, in this case, that is not what we observe.
This discrepancy is explained by the fact that the measurement errors that the different LLMs make, by comparison to the population survey benchmark, are all pretty highly, positively correlated. The LLMs make similar errors by comparison to the gold standard we are using.
- Which occupations do the LLM coders rate more highly relative to the population survey benchmark, averaging across LLMs? Which occupations do the LLM coders rate less highly relative to the population survey benchmark, averaging across LLMs? Do you notice any patterns in which occupations the LLMs tend to rate more highly than the human benchmarks, and vice versa?
## Road Maintenance Labourer        Driving Instructor            Office Cleaner
##                  -10.5365                   -7.3844                   -3.8226
##                Bus Driver        Fitness Instructor               Hairdresser
##                   -3.1690                   -1.7360                   -1.5361
##               Electrician            Aircraft Pilot                   Plumber
##                   -0.7564                    1.1810                    1.8133
##                Accountant    Primary School Teacher                 Architect
##                    3.0273                    3.0789                    3.1775
##              Head Teacher             Social Worker                Journalist
##                    3.6890                    4.4780                    6.9758
##                IT Manager General Practitioner (GP)      University Professor
##                    9.1481                   10.1548                   10.8867
##        Software Developer            Data Scientist
##                   11.7285                   12.7953
However, this is not the only pattern that seems to be present. The occupations that the LLMs rate most highly compared to the survey respondents are “Data Scientist”, “Software Developer”, and “University Professor”. The occupations that the LLMs rate least highly compared to the survey respondents are “Road Maintenance Labourer”, “Driving Instructor”, and “Office Cleaner”. The obvious contrast here is between jobs that involve acting in and on the physical world and jobs that involve processing and acting on information. Perhaps LLMs are biased towards jobs that consist of the kinds of activities that LLMs are good at?
If one wanted to further investigate the hypothesis that LLMs are biased towards occupations that involve tasks that LLMs are good at, one would also want to use the full set of occupations in the original survey data, not just the 20 I selected for this exercise. And finally, one would actually need to measure the concept of “tasks that LLMs are good at”, which might involve further expert and/or LLM surveys.
General Practitioner (GP) is an interesting case (which the LLMs rate highly relative to humans), since it has both a large information processing component of mapping evidence onto diagnoses (which LLMs are already very good at) but also a large acting in and on the physical world component. It might be interesting to examine variation across different medical specialities, which vary in the relative importance of these elements.
- Make a scatterplot with the survey gold standard as the x-variable, and which shows all of the individual LLM measured values for the same occupations as the y variable. Plot these as small points, unlabeled. Also plot the LLM averages for each occupation, using larger points and with the occupation labeled. Are the average errors of the LLMs relative to the survey gold standard systematically different between occupations with low levels of prestige and high levels of prestige?
library(tidyr)
library(ggplot2)

wide_df <- cbind(prestige_gold_standard,llm_prestige_ratings)

# Long format: one row per (observation, column) pair
long_df <- wide_df |>
  pivot_longer(
    cols = -prestige_gold_standard,
    names_to = "model",
    values_to = "rating"
  )

# LLM means, with labels
mean_df <- data.frame(
  prestige_gold_standard,
  llm_average_rating = rowMeans(llm_prestige_ratings),
  label = rownames(llm_prestige_ratings)
)

ggplot() +
  geom_abline(intercept = 0, slope = 1, linetype = "dashed") +
  geom_point(data = long_df, aes(x = prestige_gold_standard, y = rating), shape = 16, size = 1, col = rgb(0,0,0,0.25)) +
  geom_point(data = mean_df, aes(x = prestige_gold_standard, y = llm_average_rating), shape = 16, size = 4, col = rgb(0,0,0,0.5)) +
  geom_text(data = mean_df, aes(x = prestige_gold_standard, y = llm_average_rating, label = label), size = 3, hjust = 0, nudge_x = 1.5) +
  coord_cartesian(xlim = c(0, 100), ylim = c(0, 100)) +
  labs(x = "Occupational Prestige (Survey Data)", y = "Occupational Prestige (LLM Ratings)")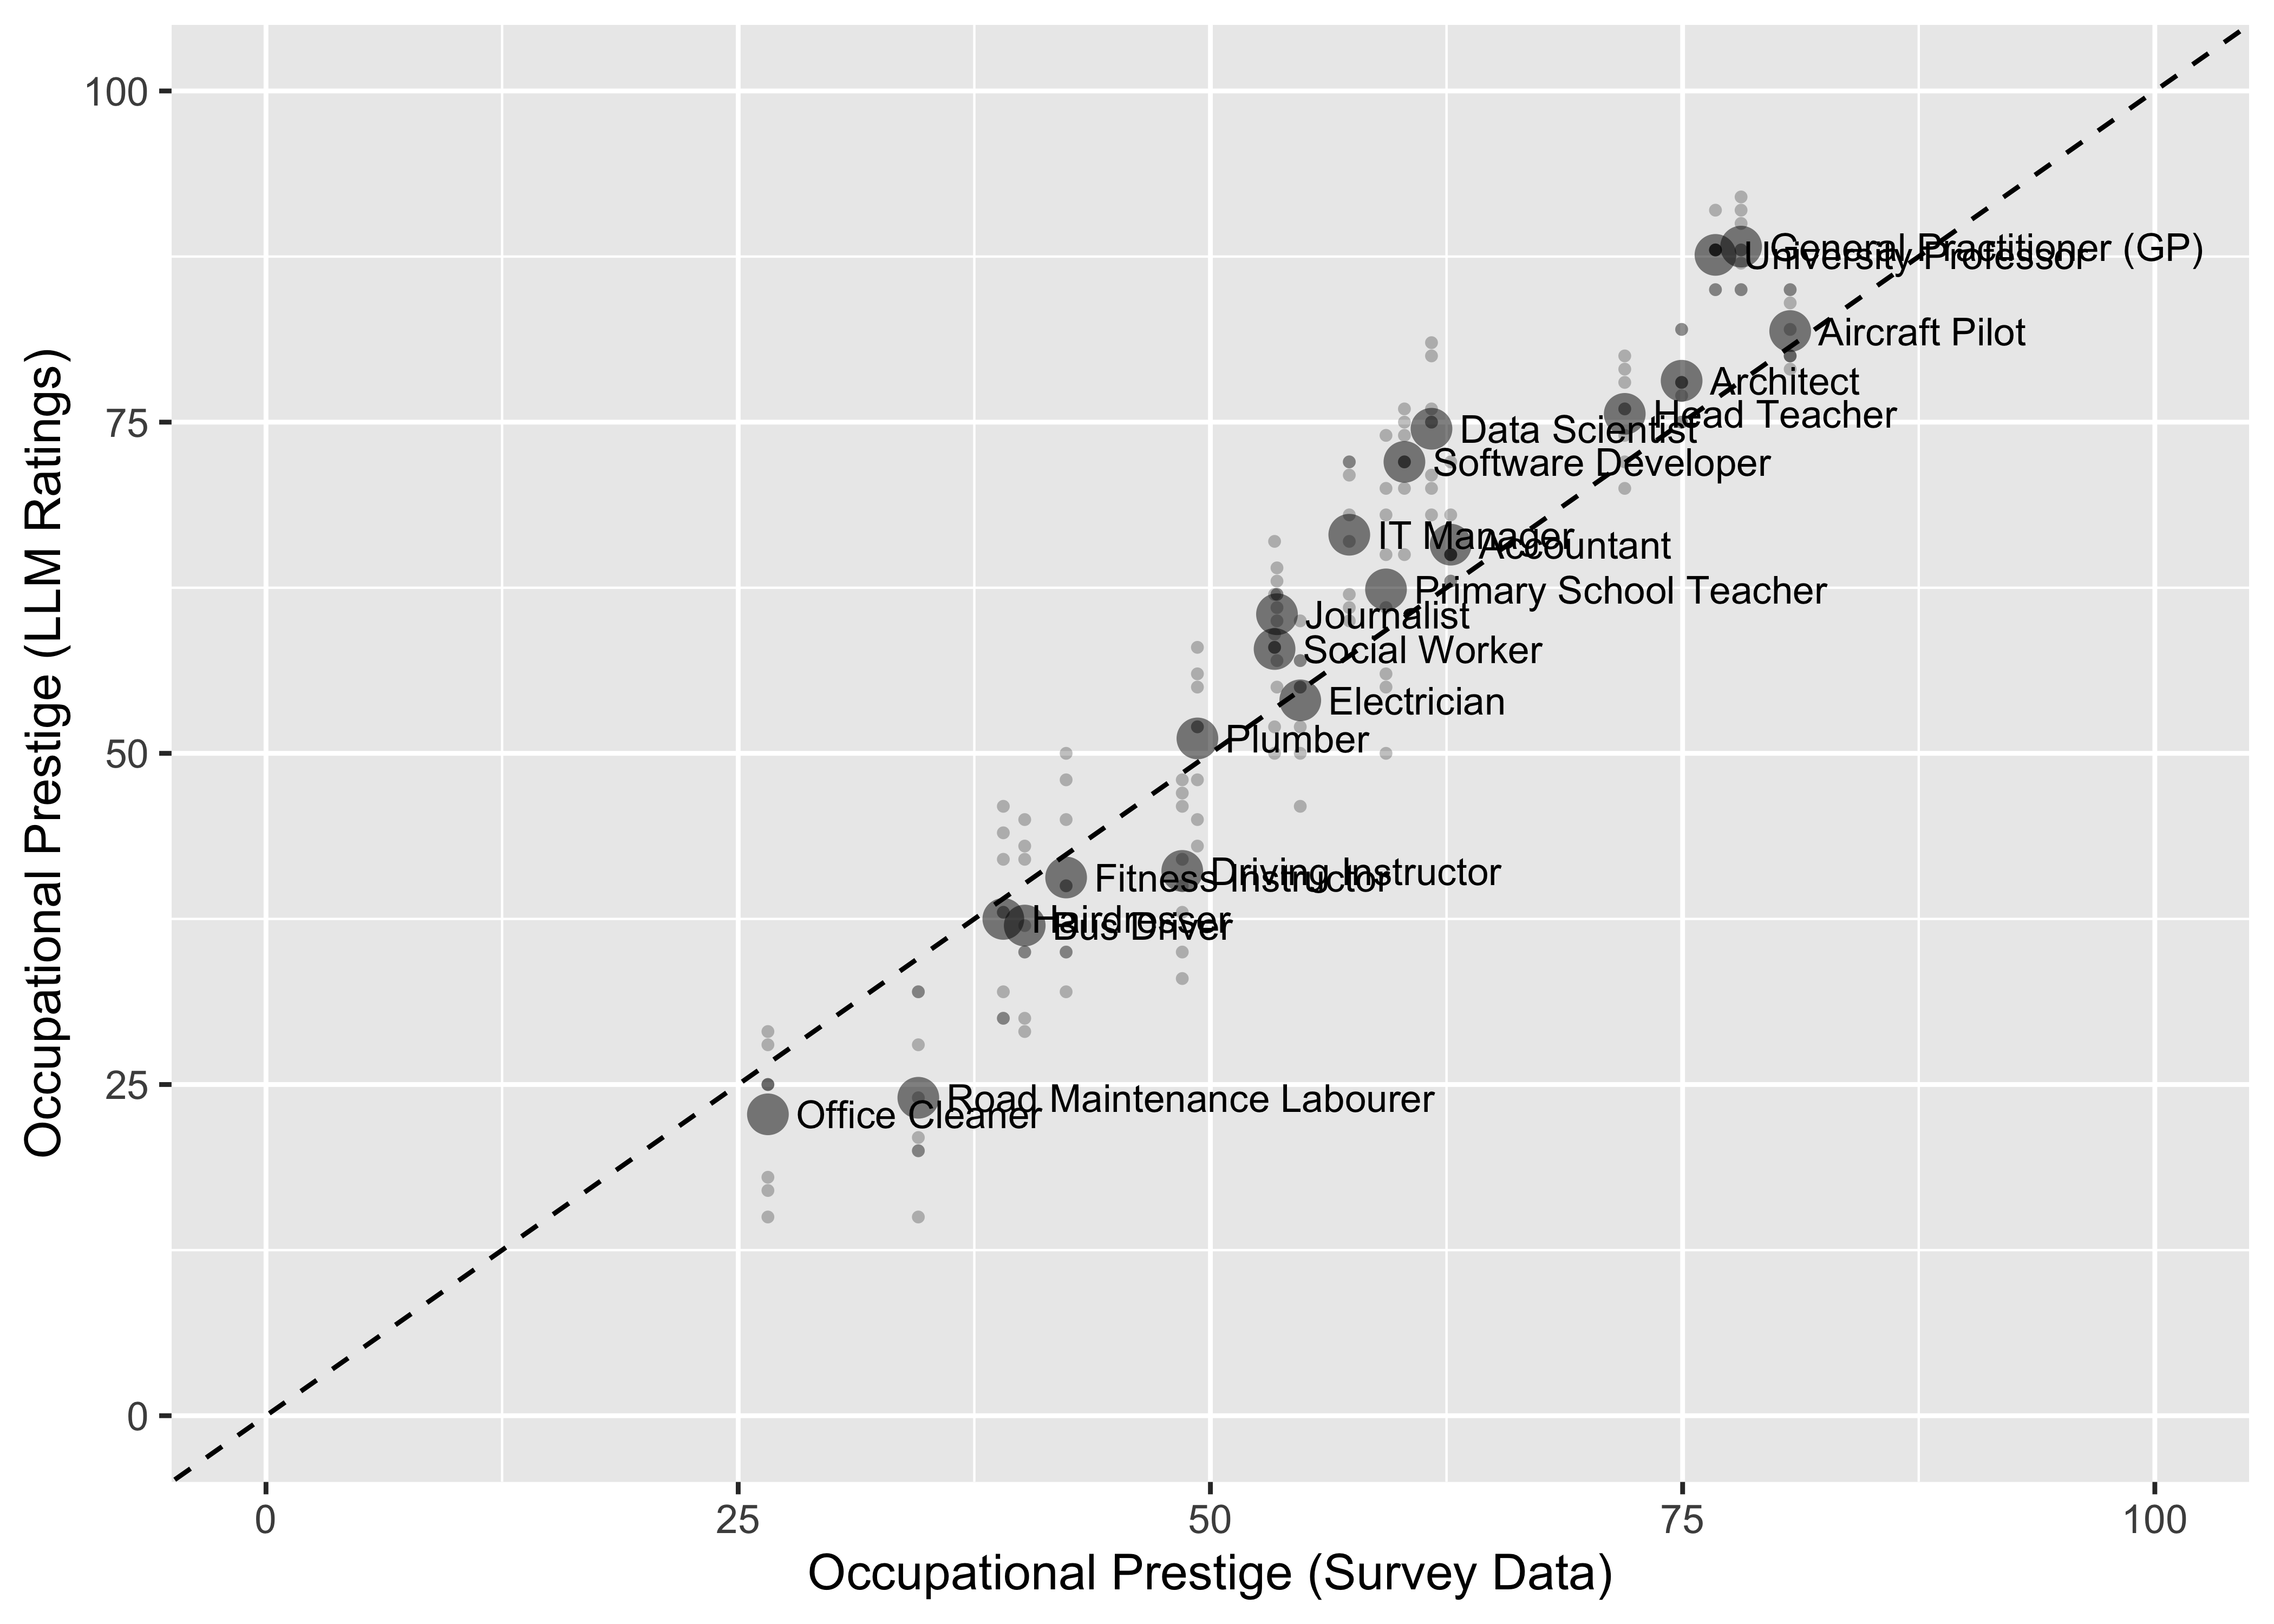
Overall, there is clear evidence of miscalibration between the LLM scales and the gold-standard, the LLMs tend to have positive measurement errors on high prestige occupations and negative measurement errors on low prestige occupations.
There are many ways to make a plot like this, don’t worry if yours looks substantially different than this one. The important thing is that your plot makes it possible to see that the occupations at high levels of prestige in the survey data tend to be rated even higher by the LLMs, and the occupations at low levels of prestige in the survey data tend to be rated even lower by the LLMs. That is, the LLMs use a bit more of the range across the positions.
Note that, while this explains a bit of the LLMs’ tendency to rate positions that involve information processing higher than humans do (these jobs tend to be at higher levels of prestige among human raters in the survey), it does not explain all of this pattern. You can still see that Data Scientist, Software Developer, IT Manager, and Journalist have high positive residuals from the trend of points, as well as from the diagonal.
- What are some reasons why it makes sense to use a population survey average as a gold standard benchmark for a concept like occupational prestige? Can you think of reasons it might not make sense to treat these data as a gold standard benchmark?
The strongest argument for the population survey gold standard is that “occupational prestige” is a sociological concept which seems difficult to separate from the judgements of people in a given society. The jobs which are more prestigious are the jobs people in a given population think are more prestigious, it is difficult to see what other standard one would use. So a population survey really seems like a very defensible gold standard.
If one wanted to argue against this, one could go in a few different directions. First, one could identify a basis for “occupational prestige” that was not based on what people in general think. Second, one could identify issues with this specific survey of occupational prestige (is it a representative sample? were the survey questions well designed? is it sampling the right population?). Third, one could identify issues with how the LLMs were prompted that might have meant that they were not targeting the same concept as the survey respondents (e.g., perhaps it is important to tell the LLM to imagine that it is a typical member of the UK public, or something like that). These three lines of potential argument are respectively “this is not the right kind of gold standard for this concept”, “this gold standard measure itself is mismeasured”, and “these measures were not actually aiming to measure the concept that this gold standard measures”. These are more general lines of criticism to consider in many validation problems.
- Now, let’s turn to the data on regulated professions/occupations. Examining the various
regulation_[llmname]variables, and using the variableregulatedas the gold standard, calculate the sensitivity and specificity of each measure against the gold standard. Remember, the sensitivity is the rate of measured positive cases among true positive cases; specificity is the rate of measured negative cases among true negative cases.
llm_regulation_variable_names <- c("regulation_gemini_3.5_flash_lite","regulation_gemini_3.6_flash","regulation_gemini_3.1_pro","regulation_chatgpt","regulation_chatgpt_thinking","regulation_claude_haiku_4.5","regulation_claude_sonnet_5.0","regulation_claude_opus_5.0")
llm_regulation_codings <- df[,llm_regulation_variable_names]
regulation_gold_standard <- df$regulated
rownames(llm_regulation_codings) <- df$occupation_title
colnames(llm_regulation_codings) <- sub("regulation_","",llm_regulation_variable_names,fixed=TRUE) # shorter variable names, not necessary to do this

# write functions to calculate sensitivity and specificity

sensitivity <- function(measure, target) {
  tp <- sum(measure == 1 & target == 1)
  fn <- sum(measure == 0 & target == 1)
  tp / (tp + fn)
}

specificity <- function(measure, target) {
  fp <- sum(measure == 1 & target == 0)
  tn <- sum(measure == 0 & target == 0)
  tn / (tn + fp)
}

# apply functions to each of the llm regulation codings

sensitivity_by_llm <- apply(llm_regulation_codings,2,sensitivity,target=regulation_gold_standard)
specificity_by_llm <- apply(llm_regulation_codings,2,specificity,target=regulation_gold_standard)

print(cbind(sensitivity_by_llm,specificity_by_llm))
## sensitivity_by_llm specificity_by_llm
## gemini_3.5_flash_lite 0.8888889 0.8181818
## gemini_3.6_flash 0.8888889 0.7272727
## gemini_3.1_pro 0.8888889 0.7272727
## chatgpt 0.8888889 0.8181818
## chatgpt_thinking 0.8888889 0.7272727
## claude_haiku_4.5 0.8888889 0.7272727
## claude_sonnet_5.0 0.8888889 0.7272727
## claude_opus_5.0 0.8888889 0.7272727There are quicker ways to write the needed code than what is shown above, again the code was written for clarity in each of the steps.
All of the models have the exact same sensitivity. It turns out this is because they all make the same coding decisions on all of the occupations that are “positives” (UK regulated professions). There is a little variation on specificity (with two of the ostensibly worse models getting one more correct than the rest of the models).
- Which occupations are the LLMs disagreeing on? Which are they getting wrong relative to the gold standard? What might we conclude from this?
# which occupations is there disagreement on?

disagreements <- which(rowMeans(llm_regulation_codings) != 0 & rowMeans(llm_regulation_codings) != 1)
print(llm_regulation_codings[disagreements,])
## gemini_3.5_flash_lite gemini_3.6_flash gemini_3.1_pro chatgpt
## Plumber 0 1 1 0
## chatgpt_thinking claude_haiku_4.5 claude_sonnet_5.0 claude_opus_5.0
## Plumber 1 1 1 1## [1] 0# which occupations are the LLMs all getting wrong?
allwrong <- which(rowMeans(apply(llm_regulation_codings,2,function(x) x != regulation_gold_standard),1) == 1)
print(llm_regulation_codings[allwrong,])## gemini_3.5_flash_lite gemini_3.6_flash gemini_3.1_pro
## Accountant 1 1 1
## Electrician 1 1 1
## Road Maintenance Labourer 0 0 0
## chatgpt chatgpt_thinking claude_haiku_4.5
## Accountant 1 1 1
## Electrician 1 1 1
## Road Maintenance Labourer 0 0 0
## claude_sonnet_5.0 claude_opus_5.0
## Accountant 1 1
## Electrician 1 1
## Road Maintenance Labourer 0 0## [1] 0 0 1## [1] "Title unprotected. Only reserved activities (statutory audit, insolvency, probate) are regulated."
## [2] "Title unprotected. Part P competent person schemes cover domestic work in England and Wales, but registration is not mandatory for the occupation."
## [3] "Operatives working on the public highway require SWQR accreditation."The only occupation for which there is any disagreement across the LLMs is “Plumber”. The gold standard says that this is not a regulated UK profession. 6 of the 8 models say that it ought to be.
All of the models think that “Accountant” and “Electrician” should be regulated professions, but they are not. None of the models think that “Road Maintenance Labourer” should be regulated, but it is. If you are interested in the details of these cases, review the note variable in the data set. In the first two cases, while they do not meet the formal definition of a regulated profession, there are elements of the work that are regulated in other ways.
- Review above how these measurements and the gold standard were constructed. How should this shape our interpretation of these patterns of the differences between them? What might be a more appropriate gold standard to use, if one could collect the appropriate data?
If you read carefully above, the LLMs were asked which occupations ought to be regulated given the definition of a regulated profession. The gold standard we are using is the actual state of UK law. There is a discrepancy here between the gold standard and what the measurement prompt actually said. The LLMs were not asked whether these professions are regulated in the UK. So this is not really an appropriate gold standard measurement for assessing the LLM’s performance at answering the question that they were asked.
If we wanted such a gold standard for this fundamentally normative question of which professions ought to be regulated, we might do something like a survey of individuals with expertise in employment regulation. A survey of the public is another option, but whether the views of the general public ought to be setting the normative benchmark for this relatively obscure question is something that not everyone would agree on (including many members of the public, who might be happy to defer to experts on such a question).
3.2 Quiz
- Which of the following are NOT elicited measures?
- A survey asking respondents how unequal their society is
- Getting research assistants to code text documents
- GDP per capita
- Looking at google review star ratings to evaluate a restaurant
- Which of these are an advantage of directly elicited measures?
- We can always be sure that the measure is close to the target concepts
- When they are available, they are usually the best measure we can get
- We can take advantage of knowledge people or LLM agents have
- We can use LLMs, which always give us the right answer
- In which of these cases are elicited measures NOT particularly useful?
- When higher quality measures are not publicly available (\(rightarrow\) self-report)
- When it is important our measure is representative of a population (\(rightarrow\) crowd judgment)
- When detailed domain knowledge is necessary to measure our concept (\(rightarrow\) expert judgment)
- When our measurement has a ratio scale
- Robot wars: LLMs vs Humans - who wins?
- Summarising generally available text information \(\rightarrow\) LLMs
- Physical or embodied experience \(\rightarrow\) Humans
- Performing repetitive tasks \(\rightarrow\) LLMs
- Measurements that represent the full diversity of views of a population \(\rightarrow\) Humans
- Giving a ‘most likely’ answer \(\rightarrow\) LLMs
- More demanding levels of measurement \(\rightarrow\) (arguably) neither
- Which of the following are appropriate ways to measure inter-coder reliability for an elicited measure?
- Compare measurements for different units from the same agent
- Compare measurements for the same unit from different agents
- Compare measurements for different units from different agents
- Compare measurements for the same unit from the same agent
- Compare measurements for the same unit from agents to a gold standard
- Which of these are direct validation?
- Asking your professor whether a measure is good or not
- Checking whether the elicited values are predictive of things they should be
- Checking if the elicited value has error relative to a direct measurement on a subset of cases
- Checking whether the elicited values are sensitive to things they should not be (e.g. question wording)
- What were the measurement problems in the self-reported phone usage example?
- On average, people consistently over or under-estimated their phone usage by a lot (\(\rightarrow\) large common bias)
- Many people over or under-estimated their phone usage by a lot (\(\rightarrow\) large individua-specific bias / low reliability)
- Measurement error was correlated with true phone usage
- Measurement error was correlated with mental health
- The gold standard is arguably low quality
- Julia is probably lying about her phone usage